← AI HoodmanNo. 004 · Embeddings

Tag Embeddings

How do you embed #cooking and #aihoodman?

01of 07
Use the arrows, swipe or the arrow keys to turn the slides. Click a slide to read it page by page.
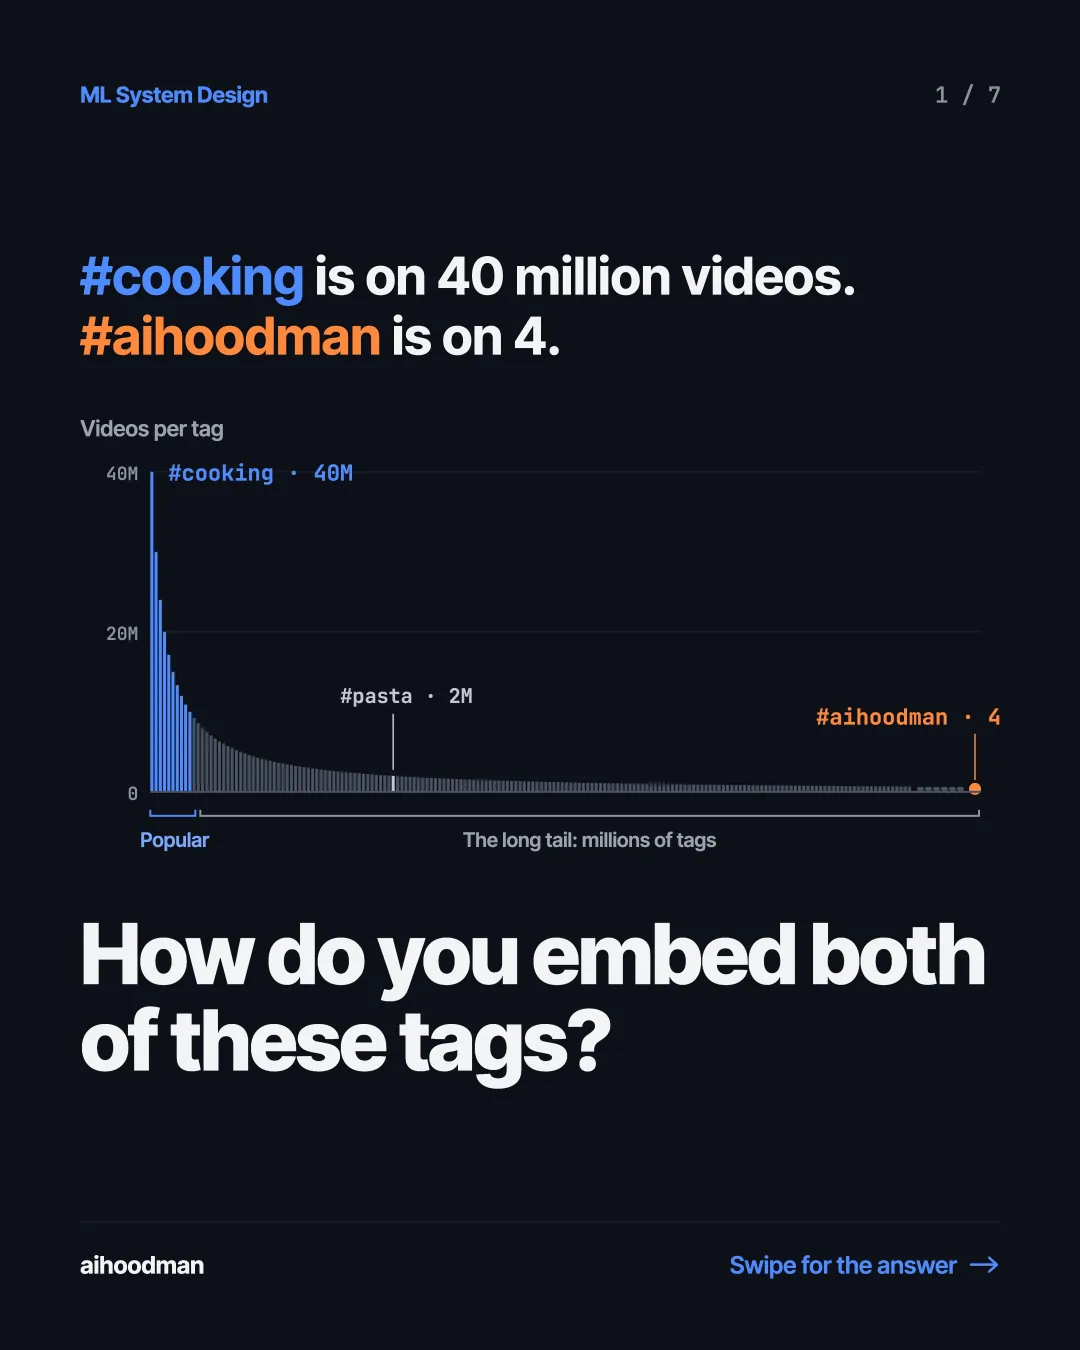
  1. Slide 1 of 7: #cooking is on 40 million videos. #aihoodman is on 4. Videos per tag 40M #cooking · 40M 20M #pasta · 2M #aihoodman · 4 0 Popular The long tail: millions of tags How do you embed both of these tags?
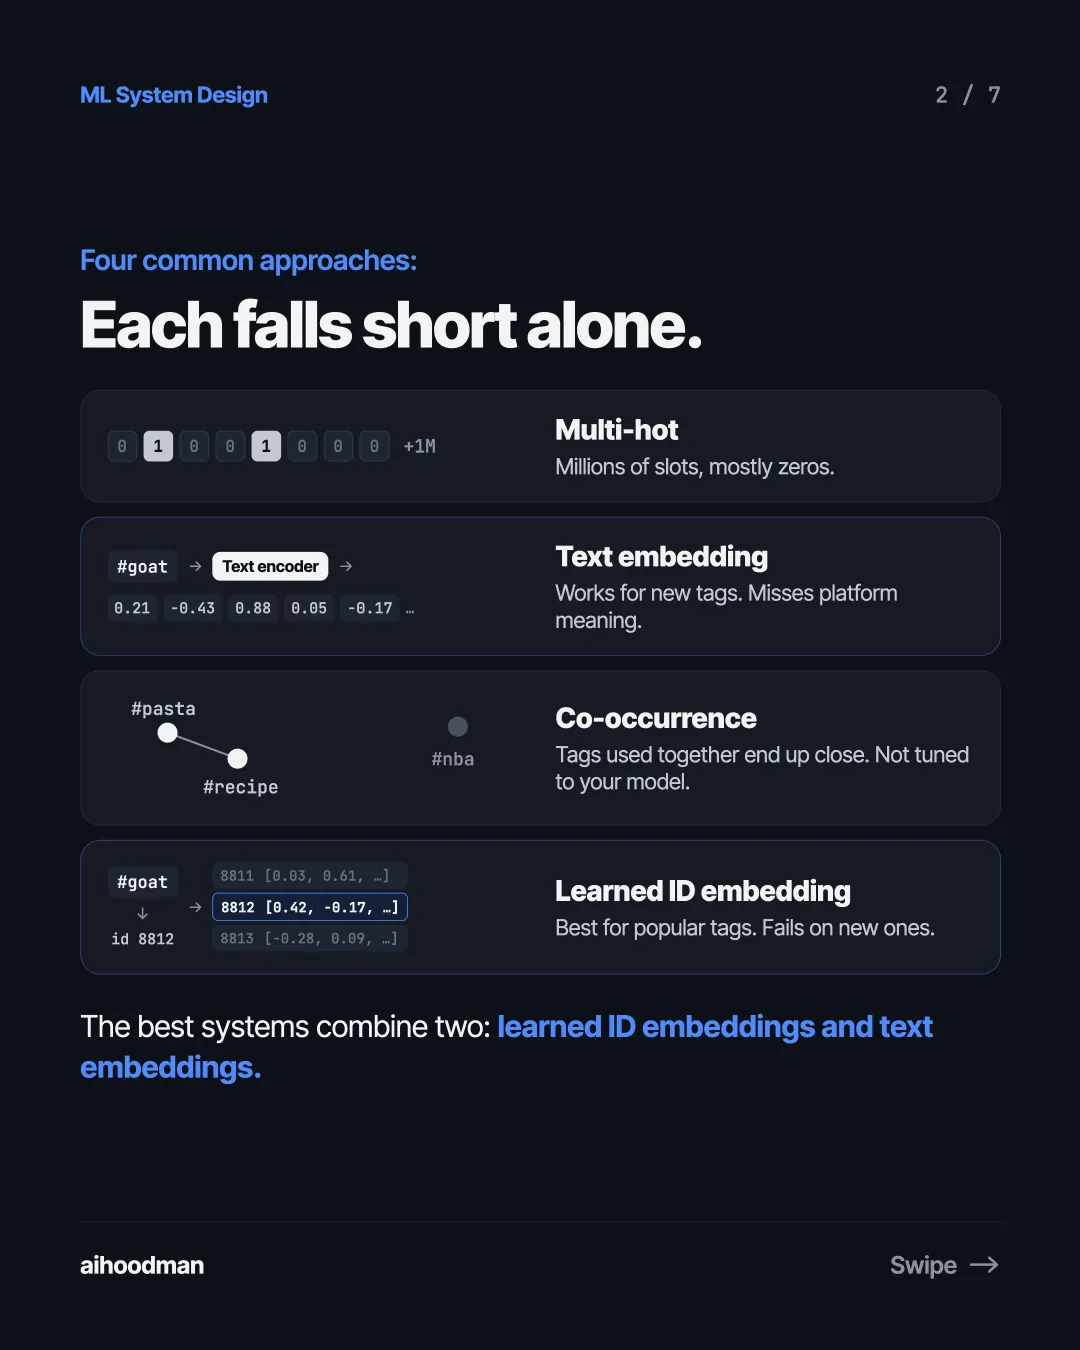
  2. Slide 2 of 7: Four common approaches: Each falls short alone. 0 1 0 0 1 0 0 0 +1M Multi-hot Millions of slots, mostly zeros. #goat → 0.21 -0.43 Text encoder 0.88 0.05 Text embedding → Works for new tags. Misses platform meaning. -0.17 … #pasta Co-occurrence #nba #recipe 8811 [0.03, 0.61, …] #goat ↓ → id 8812 8812 [0.42, -0.17, …] 8813 [-0.28, 0.09, …] Tags used together end up close. Not tuned to your model. Learned ID embedding Best for popular tags. Fails on new ones. The best systems combine two: learned ID embeddings and text embeddings.
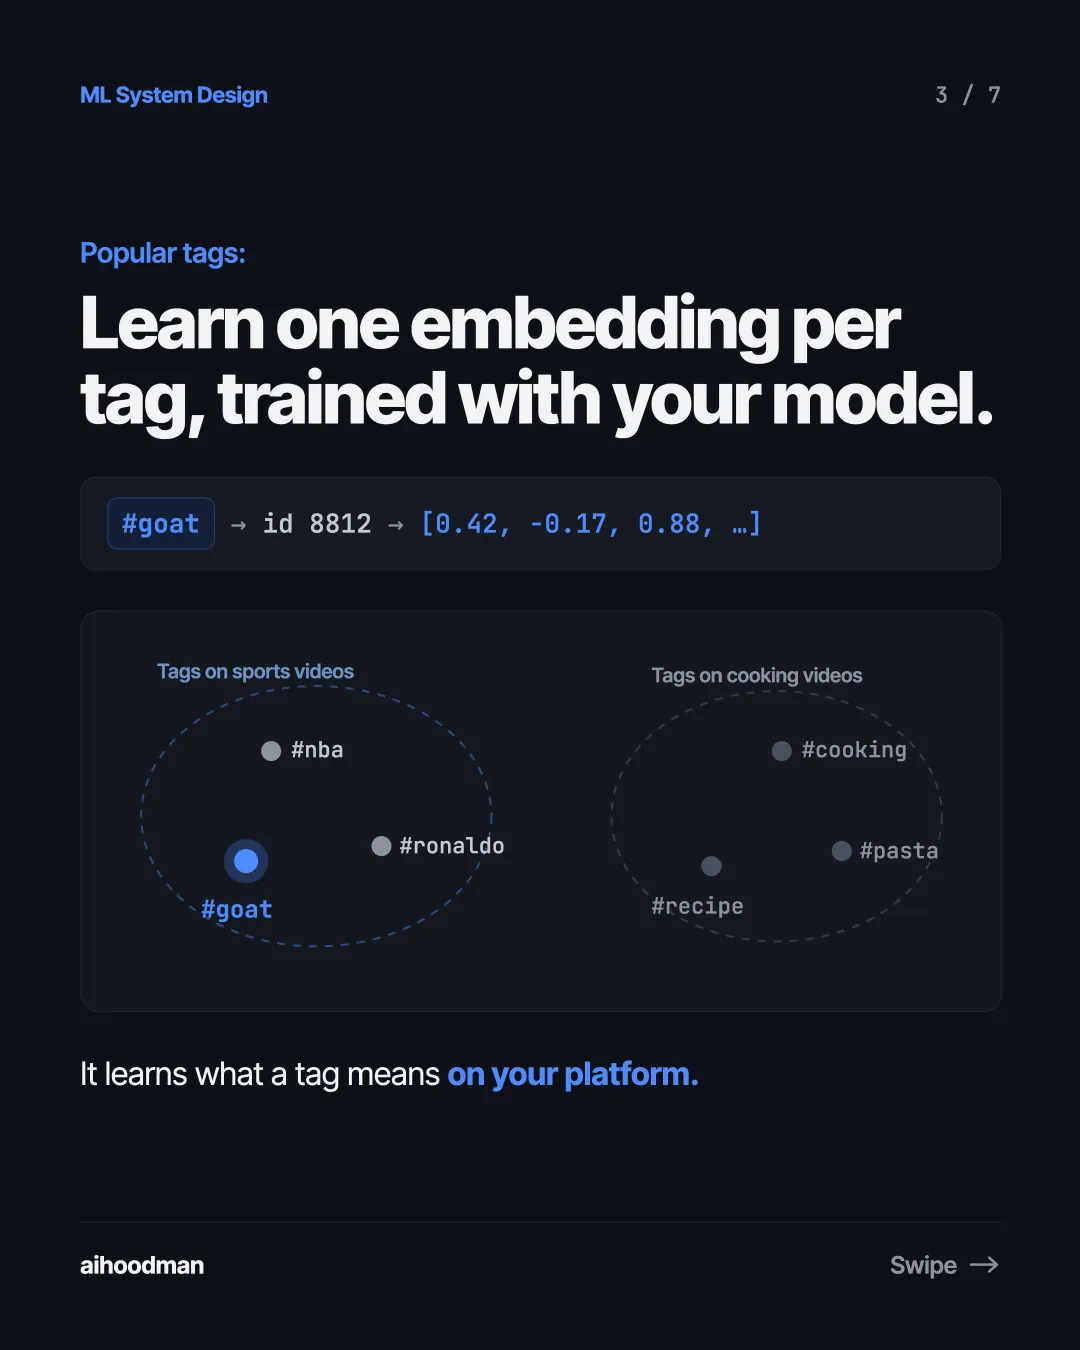
  3. Slide 3 of 7: Popular tags: Learn one embedding per tag, trained with your model. #goat → id 8812 → [0.42, -0.17, 0.88, …] Tags on sports videos Tags on cooking videos #nba #cooking #ronaldo #goat #pasta #recipe It learns what a tag means on your platform.
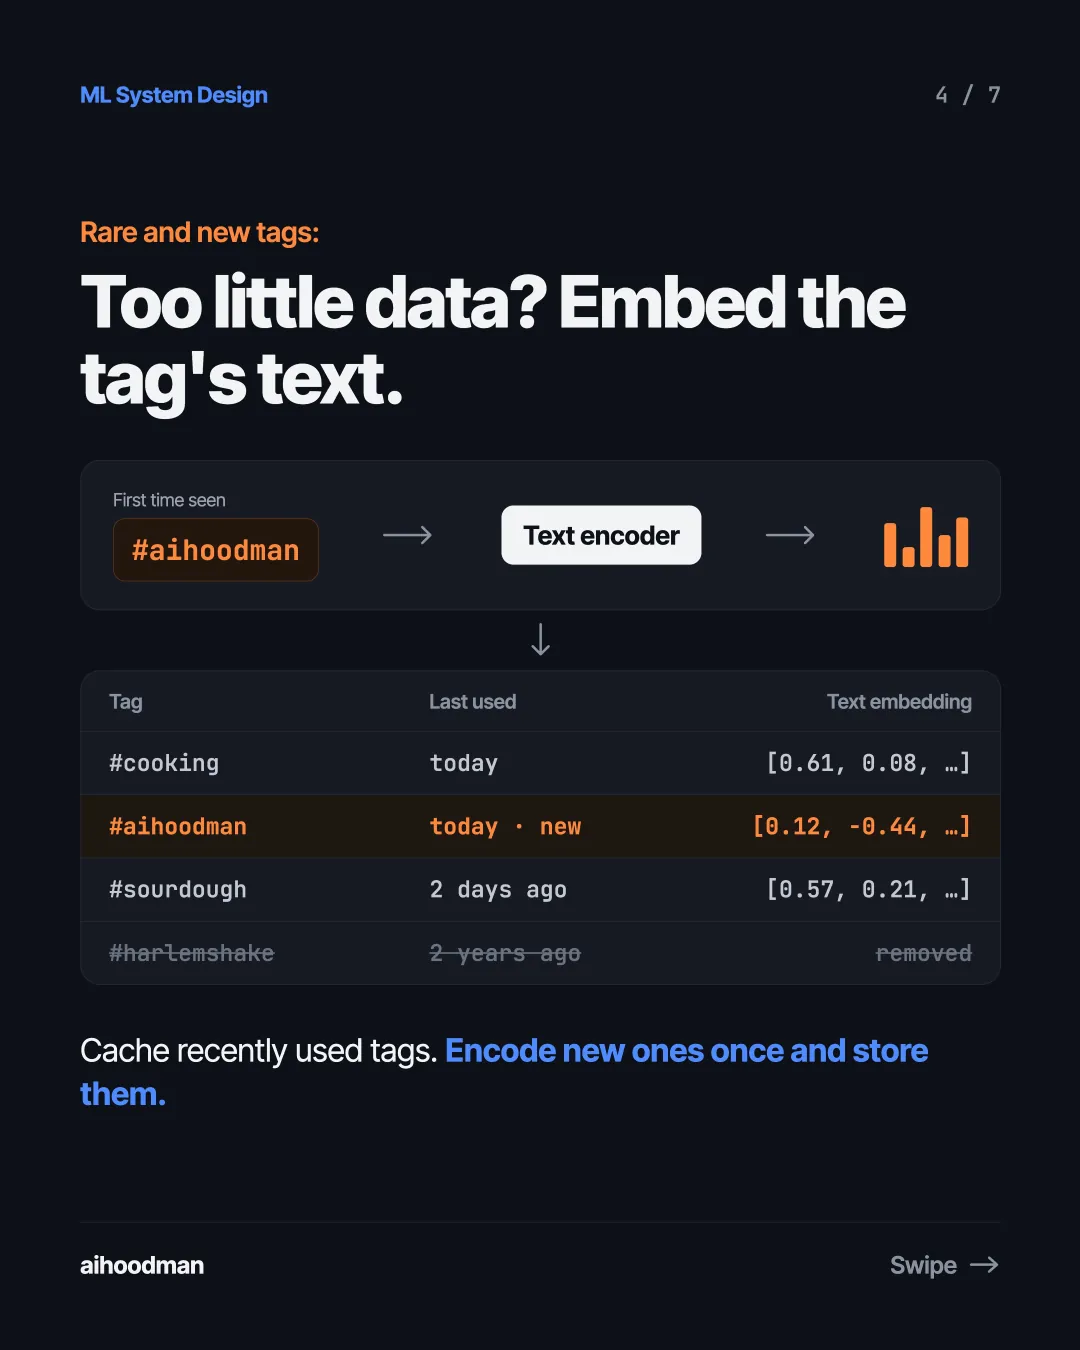
  4. Slide 4 of 7: Rare and new tags: Too little data? Embed the tag's text. First time seen Text encoder #aihoodman Tag Last used Text embedding #cooking today [0.61, 0.08, …] #aihoodman today · new [0.12, -0.44, …] #sourdough 2 days ago [0.57, 0.21, …] #harlemshake 2 years ago removed Cache recently used tags. Encode new ones once and store them.
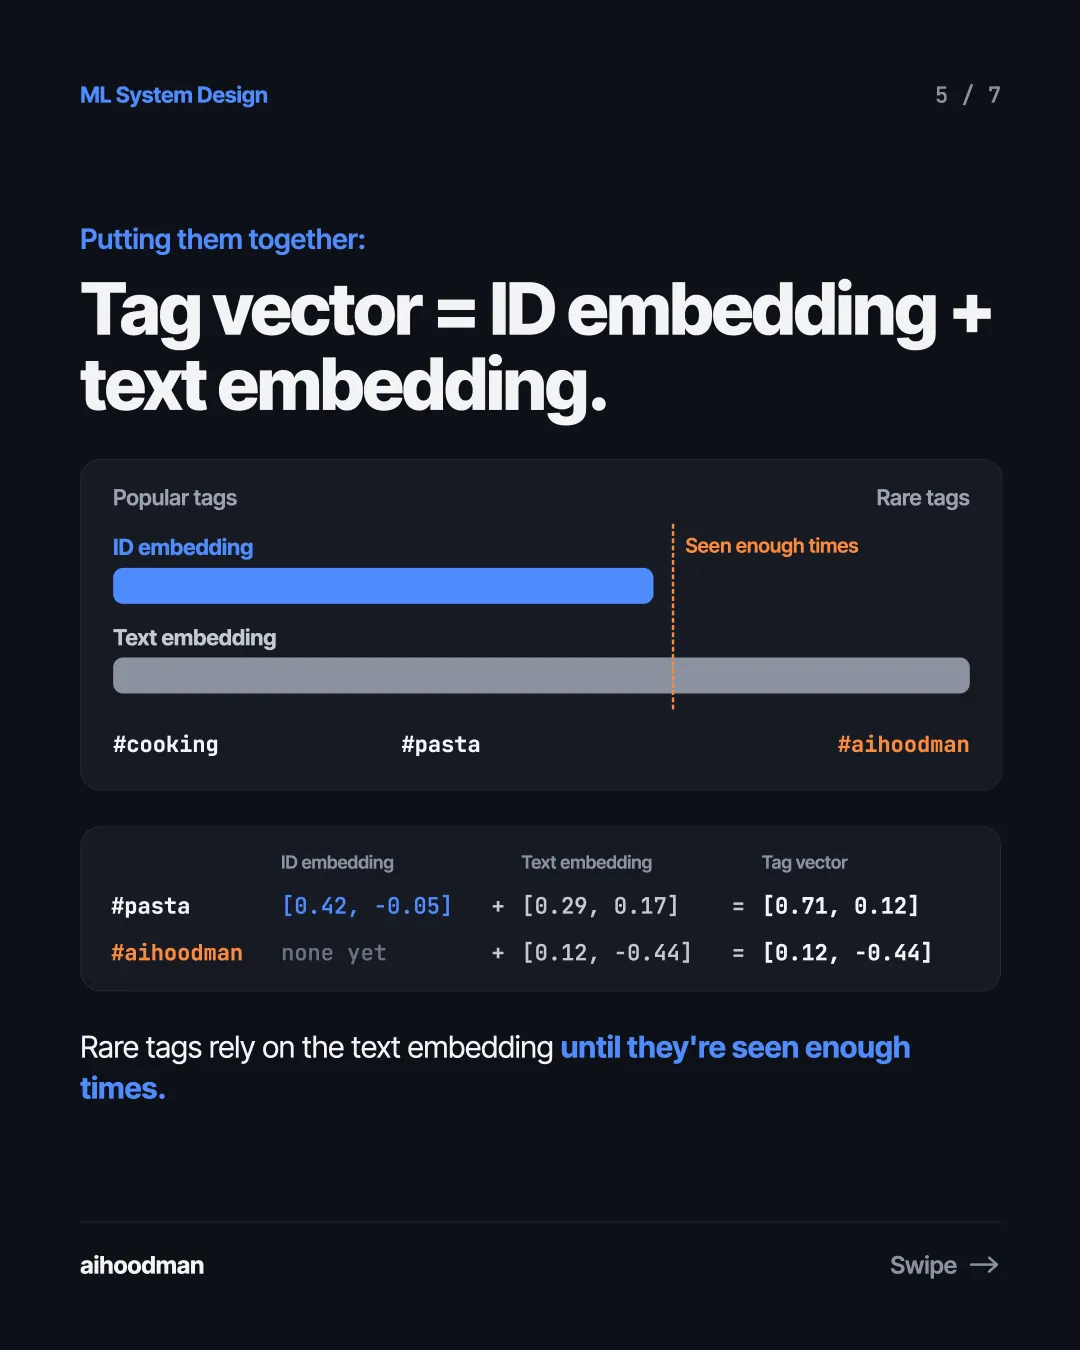
  5. Slide 5 of 7: Putting them together: Tag vector = ID embedding + text embedding. Popular tags Rare tags Seen enough times ID embedding Text embedding #cooking #pasta ID embedding #aihoodman Text embedding Tag vector #pasta [0.42, -0.05] + [0.29, 0.17] = [0.71, 0.12] #aihoodman none yet + [0.12, -0.44] = [0.12, -0.44] Rare tags rely on the text embedding until they're seen enough times.
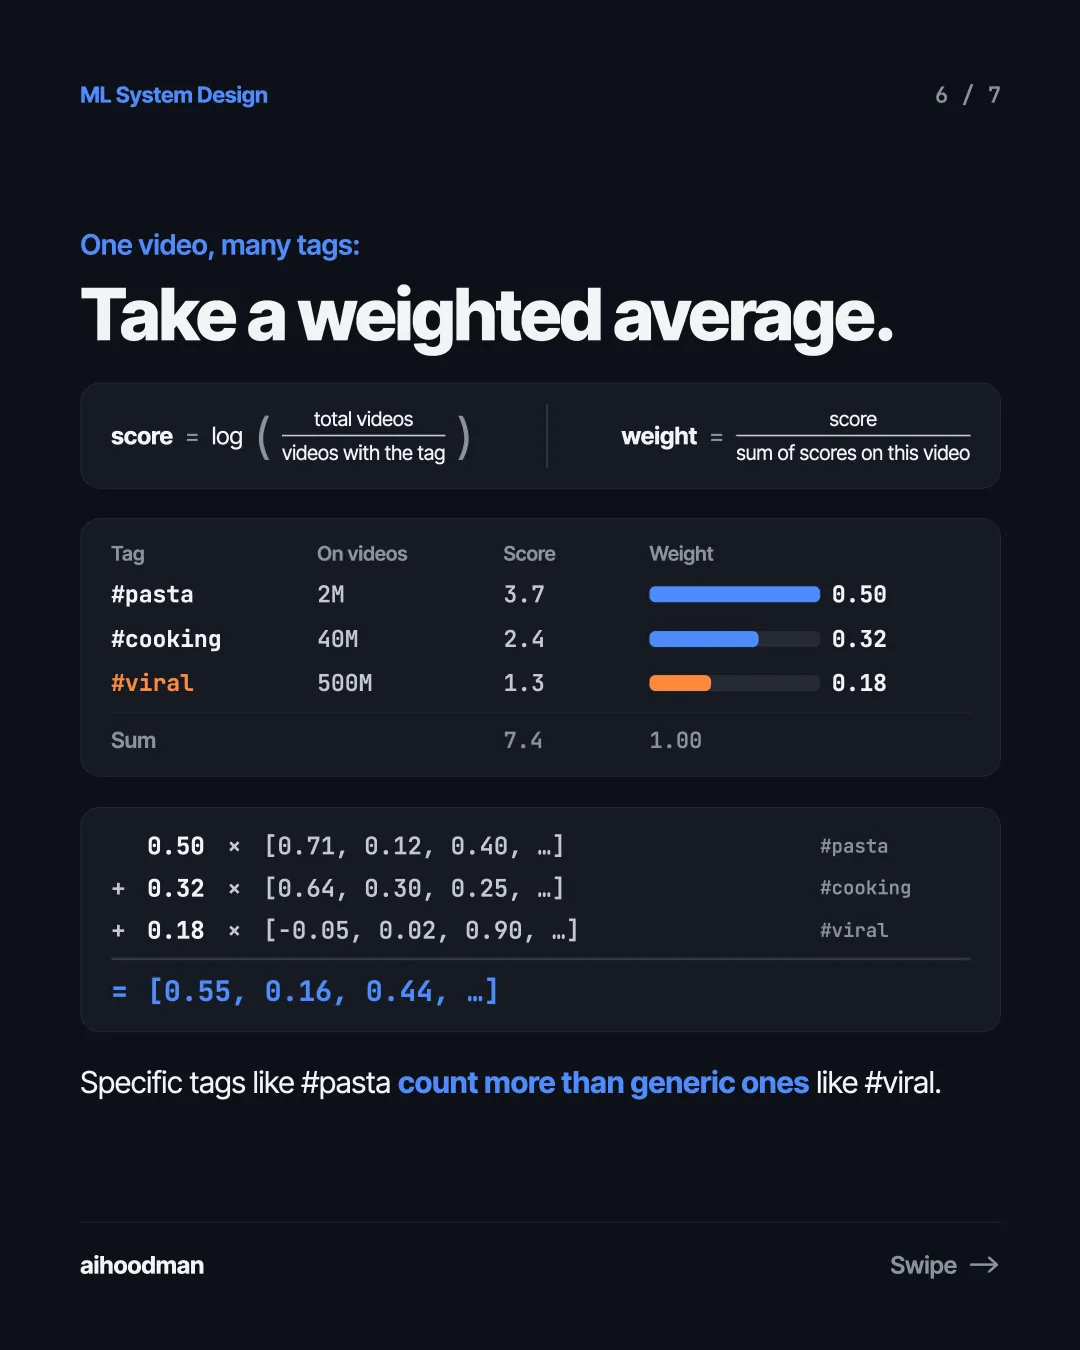
  6. Slide 6 of 7: One video, many tags: Take a weighted average. score = log total videos ( videos with the tag ) weight = score sum of scores on this video Tag On videos Score #pasta 2M 3.7 0.50 #cooking 40M 2.4 0.32 #viral 500M 1.3 0.18 Sum 7.4 0.50 × [0.71, 0.12, 0.40, …] Weight 1.00 #pasta + 0.32 × [0.64, 0.30, 0.25, …] #cooking + 0.18 × [-0.05, 0.02, 0.90, …] #viral = [0.55, 0.16, 0.44, …] Specific tags like #pasta count more than generic ones like #viral.
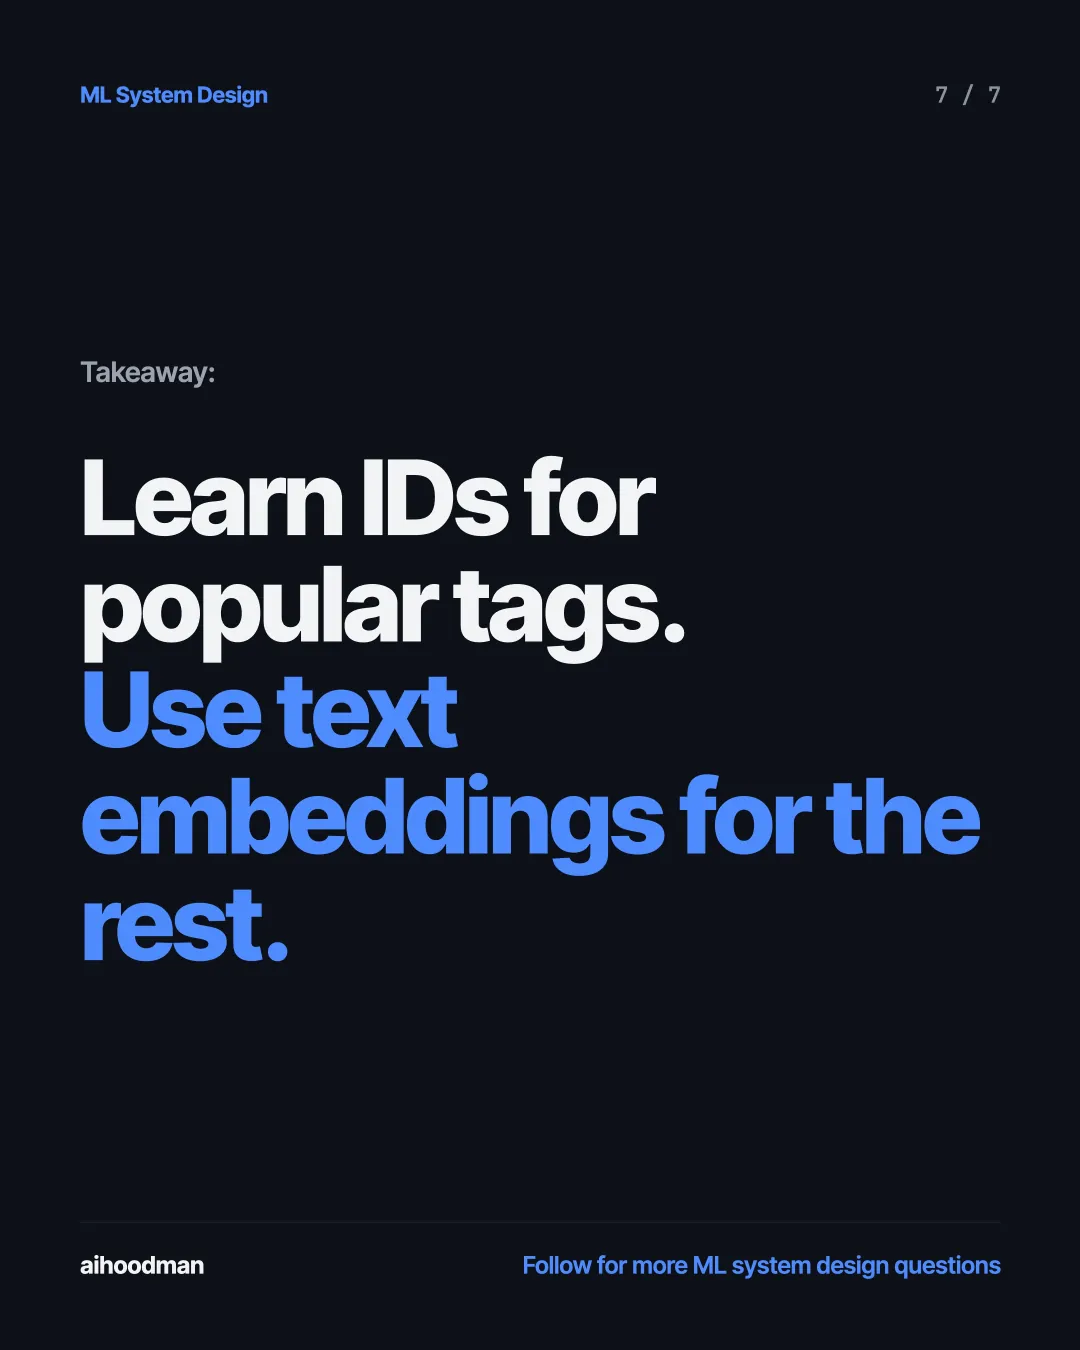
  7. Slide 7 of 7: Takeaway: Learn IDs for popular tags. Use text embeddings for the rest.

Keep reading

Tag Embeddings · 1 / 7
  1. Slide 1 of 7: #cooking is on 40 million videos. #aihoodman is on 4. Videos per tag 40M #cooking · 40M 20M #pasta · 2M #aihoodman · 4 0 Popular The long tail: millions of tags How do you embed both of these tags?
  2. Slide 2 of 7: Four common approaches: Each falls short alone. 0 1 0 0 1 0 0 0 +1M Multi-hot Millions of slots, mostly zeros. #goat → 0.21 -0.43 Text encoder 0.88 0.05 Text embedding → Works for new tags. Misses platform meaning. -0.17 … #pasta Co-occurrence #nba #recipe 8811 [0.03, 0.61, …] #goat ↓ → id 8812 8812 [0.42, -0.17, …] 8813 [-0.28, 0.09, …] Tags used together end up close. Not tuned to your model. Learned ID embedding Best for popular tags. Fails on new ones. The best systems combine two: learned ID embeddings and text embeddings.
  3. Slide 3 of 7: Popular tags: Learn one embedding per tag, trained with your model. #goat → id 8812 → [0.42, -0.17, 0.88, …] Tags on sports videos Tags on cooking videos #nba #cooking #ronaldo #goat #pasta #recipe It learns what a tag means on your platform.
  4. Slide 4 of 7: Rare and new tags: Too little data? Embed the tag's text. First time seen Text encoder #aihoodman Tag Last used Text embedding #cooking today [0.61, 0.08, …] #aihoodman today · new [0.12, -0.44, …] #sourdough 2 days ago [0.57, 0.21, …] #harlemshake 2 years ago removed Cache recently used tags. Encode new ones once and store them.
  5. Slide 5 of 7: Putting them together: Tag vector = ID embedding + text embedding. Popular tags Rare tags Seen enough times ID embedding Text embedding #cooking #pasta ID embedding #aihoodman Text embedding Tag vector #pasta [0.42, -0.05] + [0.29, 0.17] = [0.71, 0.12] #aihoodman none yet + [0.12, -0.44] = [0.12, -0.44] Rare tags rely on the text embedding until they're seen enough times.
  6. Slide 6 of 7: One video, many tags: Take a weighted average. score = log total videos ( videos with the tag ) weight = score sum of scores on this video Tag On videos Score #pasta 2M 3.7 0.50 #cooking 40M 2.4 0.32 #viral 500M 1.3 0.18 Sum 7.4 0.50 × [0.71, 0.12, 0.40, …] Weight 1.00 #pasta + 0.32 × [0.64, 0.30, 0.25, …] #cooking + 0.18 × [-0.05, 0.02, 0.90, …] #viral = [0.55, 0.16, 0.44, …] Specific tags like #pasta count more than generic ones like #viral.
  7. Slide 7 of 7: Takeaway: Learn IDs for popular tags. Use text embeddings for the rest.